Session S-031 · Experiments E-052 to E-057 · 14 August 2026
For two sessions we have been unable to tell the machine which building is which. You give it a grey drawing of the farmyard — brightness means distance — and a written description of the place, and nothing anywhere connects one to the other. So it decides for itself, and from the far end of the yard it decides wrong.
We had also concluded that a camera cannot be moved. Four separate attempts to say put the camera over there had all failed. Both of those turned out to be wrong last night, and the same one-sentence idea fixes them: the model can be told to turn round. It cannot be told which way is which.
Things we can try to command
62
That rest on one attempt
28
With no number at all, this morning
6
By the end of the night
1
My own instruments that failed
4
Section 1
First, a table of everything
The session started by writing down, in one place, every single thing we can try to ask this pipeline for — where the camera is, what it does, what the set looks like, who is in it, where they stand, how it is lit, when it cuts, what it sounds like. Sixty-two rows. For each one: what actually carries the instruction, whether it has ever been measured, with what ruler, and at how many attempts.
Twenty-eight of the sixty-two rest on a single render. That is not carelessness. A night that runs one attempt per question covers three times as many questions, and in the moment that always looks like the better trade. The table is simply the first time the bill has been visible in one place.
One render is an observation. Three is a measurement. We have a rule that says so. What we have never done is let it constrain the plan — decide up front how many three-attempt questions fit in a night, and then ask only that many.
Six rows had no number of any kind. Five of them got one during the night. The last is depth of field: in six weeks nobody has ever asked this thing for a shallow focus.
Section 2
Telling it which building is which
The drawing says “a large surface here, a smaller one there, ground running away between them”. The words say “there is a house and a barn”. Nothing says which mass is which, so the model decides from habit.
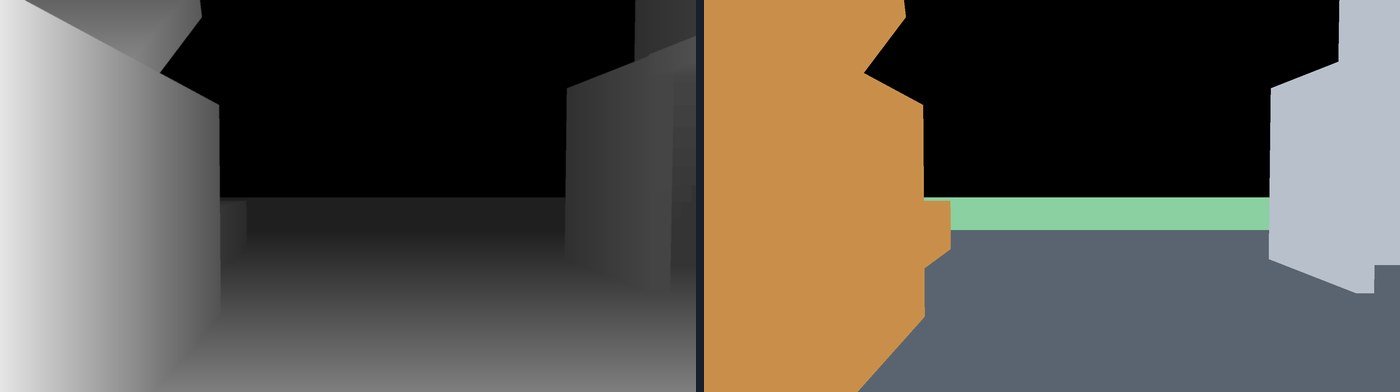
The fix was in the software we already had. You can attach a piece of text to a region of the picture rather than to the picture as a whole. And the outlines cost nothing: to make the grey drawing, the computer already works out which object every pixel is looking at, records the distance, and throws the rest away. It stopped throwing it away.
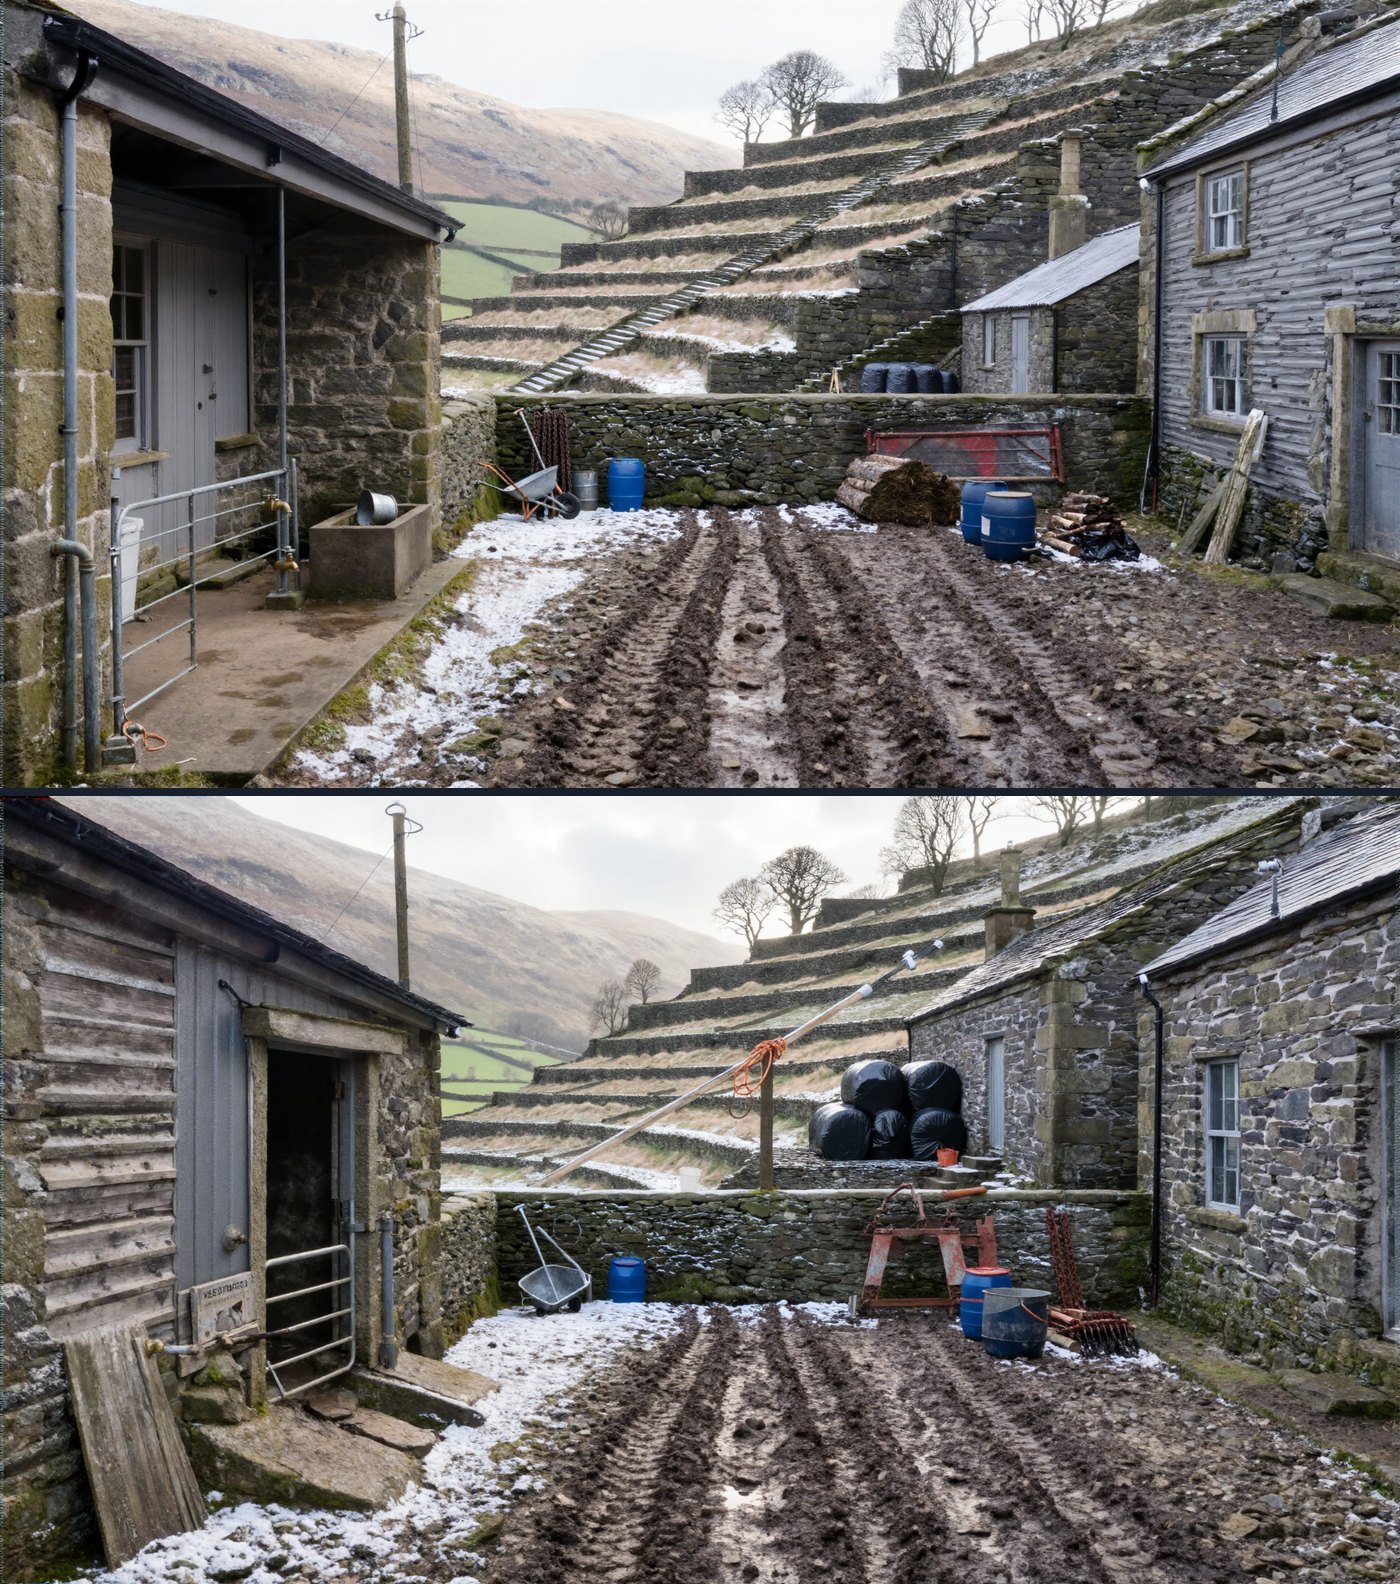
Three attempts out of three, against one out of three for the old method. It costs 95 % more time per picture, which is cheap for a shot that has to cut against another shot.
A region needs a whole prompt, not a fragment. Each region quietly generates a complete picture of its own and only its masked part is kept. Give a region one sentence and it will invent an entire scene from that sentence, then hand you the corner you asked for.
The obvious alternative is to make the machine obey the drawing more strictly. Twelve pictures say no — and say something sharper than “it does not help”. It changes what things are made of.
A footnote that turned into the best lead of the night
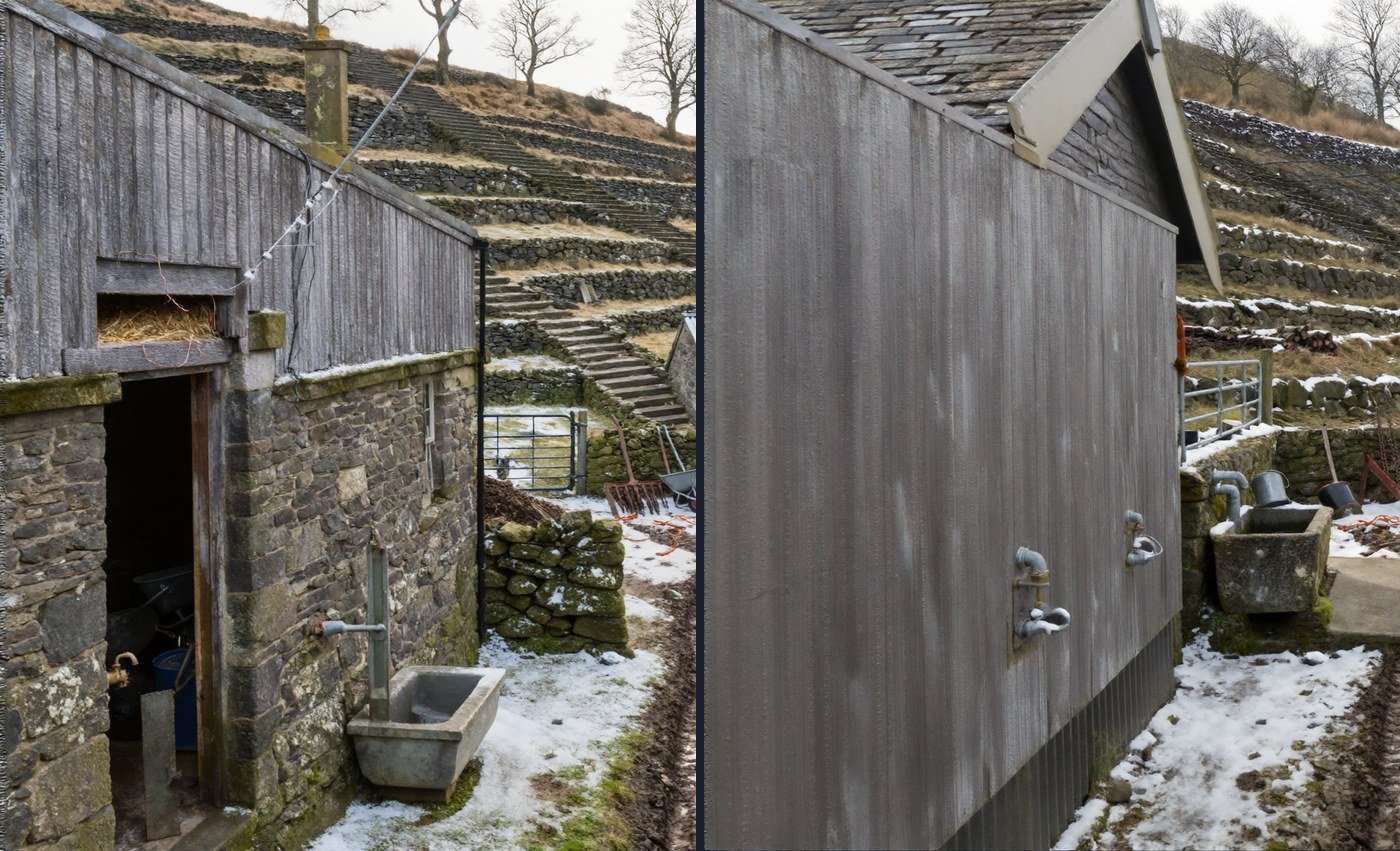
While proving that the coloured outline picture is useless as a drawing, I fed it to a second input on the same component that we have never once connected — and the machine handed it straight back.
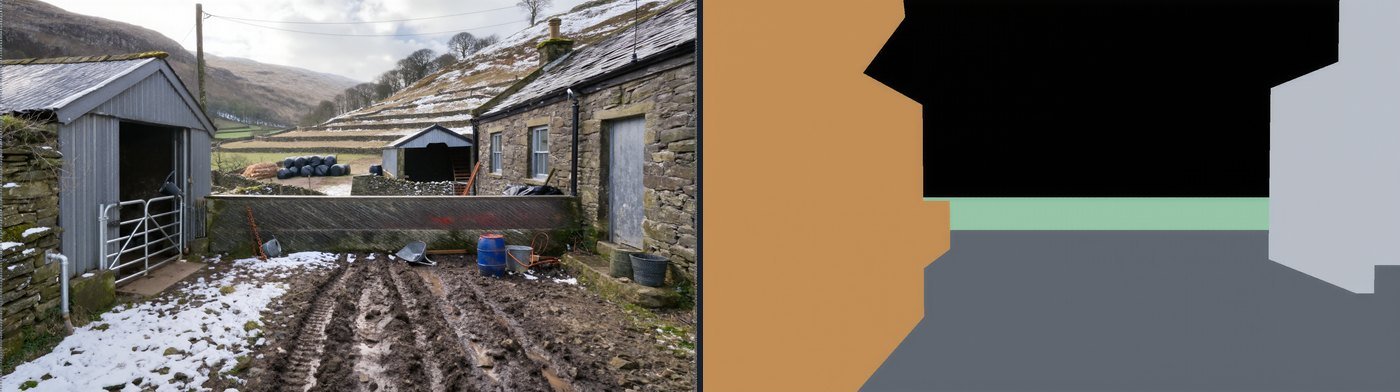
It reproduces what you give it more exactly than any other control we have, and it beats the depth drawing when the two disagree. The obvious use is continuity: hand it the previous shot’s background and mask only the part that must change, so the two shots are not merely described the same — they are literally the same pixels. Nobody has tried that yet. One warning that cost me a render: the mask marks what to regenerate, not what is known, and the software flips it before use. Give it a white mask and you get your control back byte for byte, and it looks like a dead channel.
Section 3
And then the camera moved
We can tell the camera what to do — a pan swings the frame about half its width, an arc about seventy per cent. We have never been able to tell it where to be. The background picture carries the new position and the render ignores it. Seven hundred words of careful framing language moved the actor 1.6 percent in the wrong direction.
But there is a feature we had never pointed at the problem. You can put two camera setups inside one render and say when to cut between them. The makers describe it as being for “shots that must match spatially”. Nobody had ever asked it for a different position.
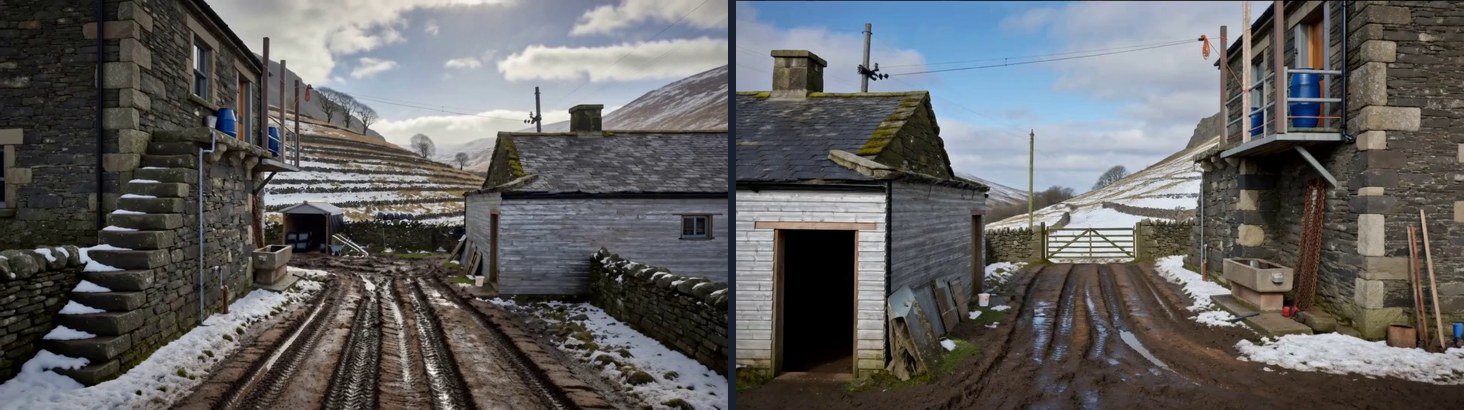
So: one render, eight seconds, cut at four, and the second shot described as “the opposite end of the same yard, eighteen metres from where it stood, looking the other way.”
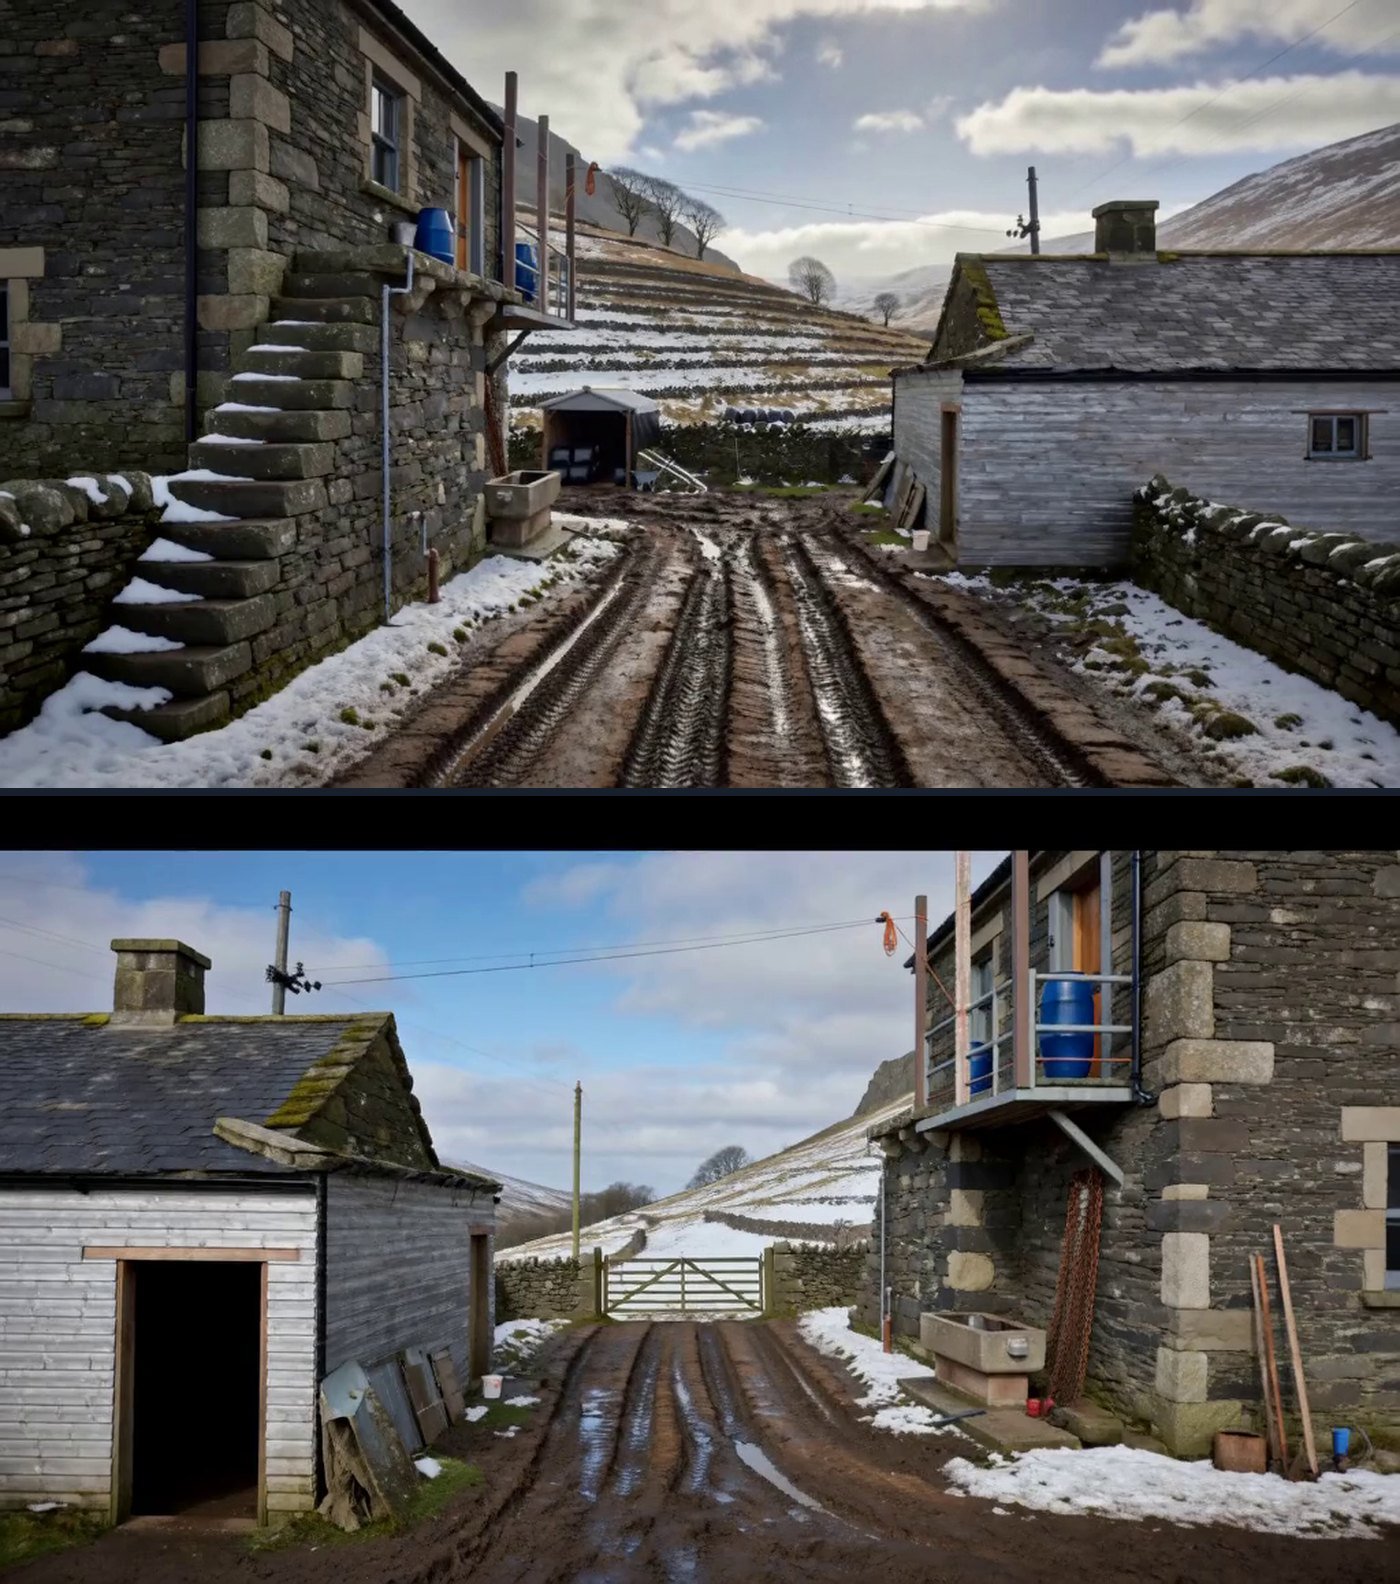
The cut was asked for at frame 96 of 192 and landed at 96, 93 and 89 across three attempts. Both buildings swapped sides correctly in all three.
And this is the sentence I would keep if I could keep only one. We spent two sessions failing to tell the model that the barn is on the east side. That is an absolute fact about the world, and it has never once landed, at any setting. “The opposite end of the same yard” is a relation between two shots it is making together, and it landed first time. The model can be told to turn round. It cannot be told which way is which.
Section 4
Where the actor stands, and why neither method obeys you
There are two ways to make a moving shot here, and we have always chosen between them on one question: does this shot need the actor’s real face? The expensive method keeps the face and invents its own farm. The cheap one reproduces our farm exactly and has no slot for a photograph at all.
This week added a third thing to weigh, and it is worse news than the other two. Neither method does what the instruction says about where the man stands. Each simply has a habit. Asked for walks away down the yard, stops in the middle, back three-quarters to camera, small in frame, at three random seeds:
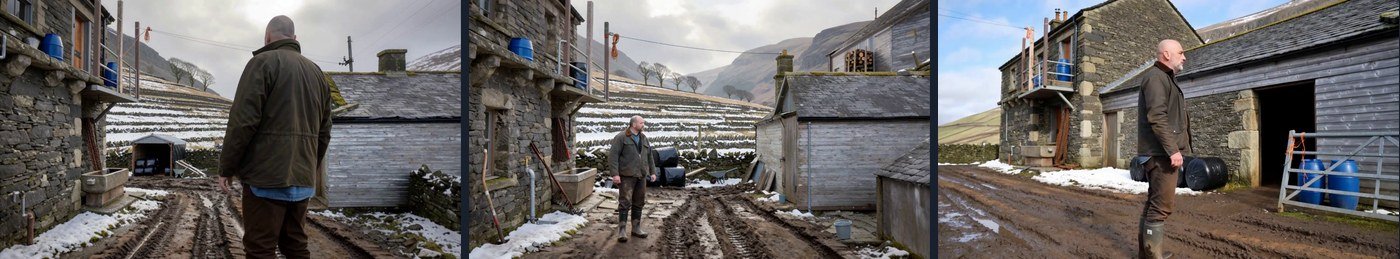
So the useful rule turns out to be about framing, not about faces. Shoot wides and full-lengths on the cheap method with an ending picture, where the man can be put at 43 % of the frame and kept there. Use the face-keeping method only for shots that want him large and near — a mid or a close-up — because that is what it does regardless of what you write.
Section 5
Four of my own measuring instruments failed
Every one of them was checked first against pictures whose answer was already on record. Every one of them failed that check, and none of their numbers is used anywhere.
The first was going to score which building landed where by comparing brightness: the house is pale limestone catching a bright sky and the barn carries the one dark thing in the frame. Run on six pictures whose answer was known, it got all six wrong — and the reason is the most useful thing in the whole experiment. The buildings do not swap. They converge. Both masses were coming out as the same interchangeable grey stone volume, with no boarding, no stair and no doorway. There was never a side to measure.
The last one was worse. It compared the colours before and after the camera moved, and reported no change in all eighteen frames — while the picture plainly showed the buildings on opposite sides. A colour histogram cannot see a camera move. Two views of one farm in one light have almost identical colours, which is the whole point of a set.
Choose the measure from what the two cases actually differ in, not from what is easy to compute. Two views of one set differ in geometry, and nothing about a colour histogram is geometric.
Section 6
Two old rules re-run, and a soundtrack found in the bin
Two rules that had hardened out of single observations were run again properly, at three attempts each with the variable actually isolated. One lived. Naming more materials in a prompt still buys no extra detail — the whole ladder from eight materials to forty spans less than a fifth of the wobble between two attempts at the same thing.
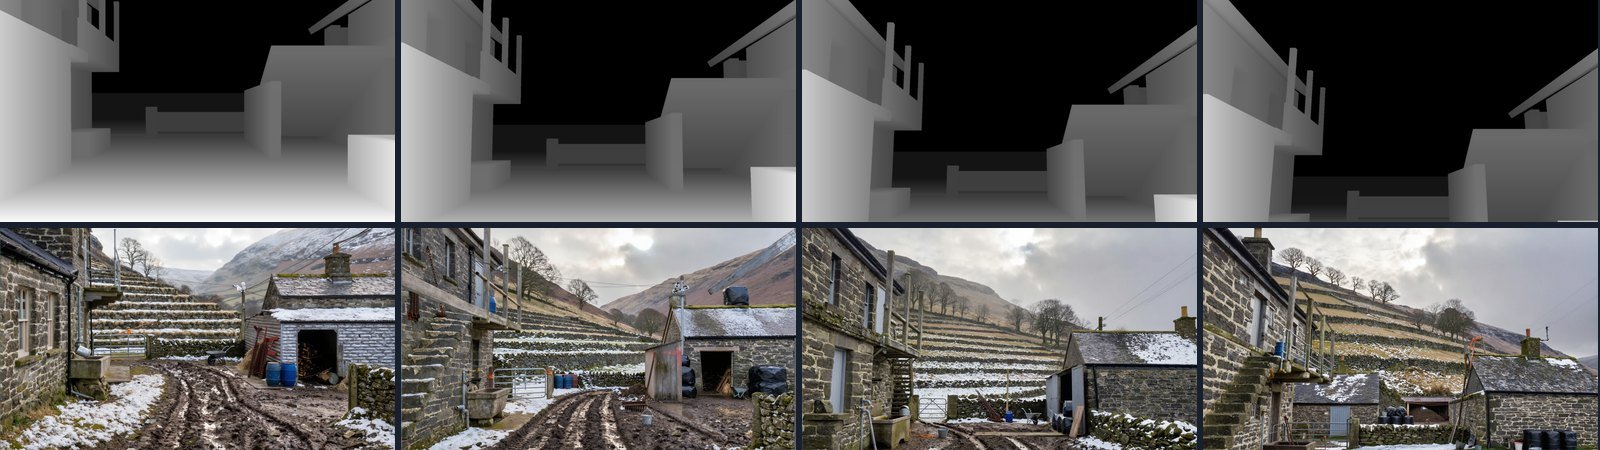
One died. We believed a drawing that was more than about a third empty stopped working. Tilting one camera up in steps, so that emptiness was the only thing changing, moved obedience by less than the noise across the whole range from a fifth to a half empty — and the drawing we had blamed measures 44 %, right inside the range where nothing happens. What is actually wrong with that drawing is that the part which is not empty has no structure in it at all. It is a picture of a floor. So the words supplied everything, including a farmhouse the camera was pointing away from.
And the smallest, most embarrassing find. Our audit of the nine-shot sequence says the cheaper of our two video methods “produces no audio track”, so a fully written sound plan — wind, cattle, water on stone, crows across the valley — was thrown away unused. It produces audio on every clip; all eighteen carry a real soundtrack forty to sixty decibels above silence. Writing the sound plan into it makes the result five decibels louder and, more tellingly, four times more consistent between attempts.
What went wrong is smaller than a missing feature. The expensive method takes six labelled boxes, one of which is called soundscape. The cheap one takes a single free-text box. Nobody ever put sound in it, because there was no box with its name on.
Honest limits. One farm, one pair of camera positions, three random seeds each. That is enough to overturn “there is no way to do this”, which is what these arms were for. It is not enough to quote a success rate. And the camera result is unproved on the method we actually shoot plates with — a picture that is right and a moving shot that is wrong would be worse than neither.